MLOps and AI Operations
Our MLOps services build the pipelines, deployment, and monitoring that turn a working model into a system your business can actually depend on every day.
The Gap Between a Model That Works and a System That Runs
A model that scores well in testing is maybe 30% of the job. The rest is everything that has to exist around it: somewhere it can run reliably under real load, data pipelines that feed it fresh clean inputs, and monitoring that notices when accuracy slips.
This is the work that decides whether AI becomes part of your operations or stays a project someone did once.
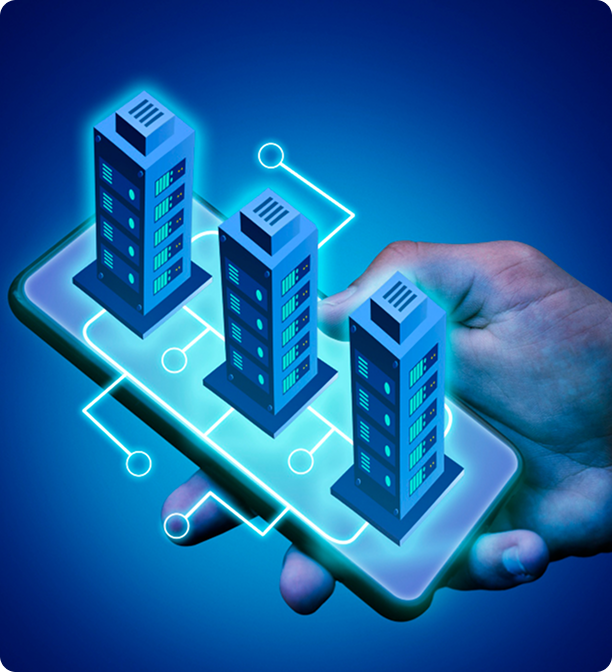
Scalable hosting, failover, and responsive inference APIs under production traffic.
Our MLOps Services
MLOps Consulting and Assessment
We review how your models are built, deployed, and monitored today, then give you a plan with the gaps ranked by risk. You get an honest assessment even if you don't continue with us.
Model Deployment
Models served as reliable APIs or batch jobs, with autoscaling, versioning, and the ability to roll back instantly when something goes wrong.
Pipeline Automation
Automated pipelines for data preparation, training, evaluation, and deployment. Retraining becomes a routine that runs, not a task someone remembers to do.
Monitoring and Drift Detection
Tracking for accuracy, data drift, latency, and cost on live traffic. Alerts fire when performance slips, before your users are the ones who notice.
LLMOps
Operations built specifically for LLM systems: prompt versioning, evaluation sets, output quality tracking, token cost monitoring, caching, and safe migration when a provider deprecates a model.
Feature Stores and Data Infrastructure
Consistent feature definitions between training and production, so the model sees the same shape of data in both. This is the source of a surprising number of accuracy problems.
CI/CD for Machine Learning
Automated testing and deployment for models, the same discipline your software already has. Every model change gets evaluated before it reaches production.
Cost Optimization
Right-sizing infrastructure and models, caching repeated calls, batching where it helps, and routing simple requests to cheaper models. Most systems have real savings in them.
MLOps or LLMOps?
Both put AI into production, but the failure modes are different.
Which does your system need?
Most businesses now run both. We cover both, and we'll tell you which one your system actually needs rather than selling you the larger package.
Who This Is For
Models unready for production
DeploymentYou have models that work in testing but haven't reached production.
Untracked live accuracy
MonitoringModels are live but nobody knows if they're still accurate or drifting.
Uncontrolled climbing AI costs
Cost ControlYour AI costs are climbing and you can't see which part is responsible.
Single-person manual retraining
AutomationRetraining is a manual job that only one person knows how to do.
Scaling beyond one model
ScalabilityYou're scaling from one model to several and the infrastructure is getting fragile.
How We Work

1. Assess
We review your models, data pipelines, infrastructure, and deployment process. You get a written assessment with the gaps ranked by risk and effort.

2. Prioritize
We recommend where to start, usually whatever is most likely to break or cost the most. You see the reasoning.
3. Build
We build the pipelines, deployment, and monitoring, working inside your existing cloud and tooling rather than introducing a new platform.

4. Hand over
Documentation and a walkthrough so your team can run it. If you'd rather we ran it, our support plans cover that.
Why Choose SolutionsLoft for MLOps
We build what you'll actually maintain
A pipeline your team can't operate is worse than the manual process it replaced.
Your stack, not ours
We work inside your cloud and tooling instead of pushing a preferred platform.
Cost is part of the design
We measure and control spend from day one, not after the first surprising invoice.
Full-stack under one roof
The same team handles the models, the infrastructure, and the applications around them.
Documentation and handover included
You should be able to run it without us.
Technologies We Work With
We build on whatever your team already runs. Adding a new platform to an already fragile setup rarely helps.
 Airflow
 Apache Spark
Frequently Asked Questions
Let's Build Something Worth Launching
Have an idea, product, or challenge? Let's bring it to life fast, smart, and beautifully executed.
Ready to Kick Off Your Project? Let's Get Started Together!
We'll schedule a call to discuss your idea. After discovery sessions, we'll send a proposal, and upon approval, we'll get started.
Not ready to submit the form?
No worries! If you’re not ready to fill out the form, simply click the button below to schedule a quick call with our sales manager. We’ll discuss your project, understand your needs, and explore how we can help you move forward.
No pressure, no obligation. Let's talk!
Is Your Model Actually in Production?
Tell us what you've built and how it runs today. On a free call, we'll tell you what's missing between where you are and a system your business can rely on.